

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in NYC, NY
Professional Services • Consulting
Own the company’s AWS infrastructure, Kubernetes platform, Terraform provisioning, deployments, security stack, and CI/CD processes. Drive GDPR and ISO 27001 compliance milestones, ship infrastructure changes quickly, and use AI coding agents daily. The role also involves training and hiring team members, collaborating with the founding and engineering teams, and supporting scalable, secure platform growth.
Top Skills:
Ai Coding AgentsAWSCi/CdKubernetesTerraform

Fintech • Financial Services
Support enterprise multi-cloud operations across Azure, GCP, AWS, and OCI. Manage Kubernetes, Linux, databases, infrastructure provisioning, observability, vulnerability remediation, incidents, releases, capacity, resiliency, governance, and AI/ML platform services. Automate operational processes with Terraform and scripting languages, maintain documentation, and participate in on-call rotations.
Top Skills:
AksAWSAzureAzure Sql Managed InstanceBashGoogle Cloud PlatformKubernetesLinuxModelopsOracle Cloud InfrastructureOracle DatabasePowershellPythonQualysSplunkTerraformWiz
Healthtech • Software
Own the reliability, security, availability, backups, disaster recovery, deployments, and hosting of Windows- and Linux-based production environments. Manage servers, networking, access controls, monitoring, vulnerability remediation, high availability, recovery testing, CI/CD support, infrastructure upgrades, and deployment automation. Evaluate cloud and hybrid-cloud modernization strategies while coordinating incidents, vendors, and technology lifecycle activities.
Top Skills:
.NetAWSAzureCi/CdDnsFirewallsGCPIisIso 27001JavaScriptLinuxMicrosoft TfsSQLTcp/IpVpnWindows Server

Consumer Web • Fintech • Insurance
Leads organization-wide SRE strategy and builds reliable, scalable AWS and Kubernetes infrastructure. Establishes SLOs, observability, incident response, disaster recovery, and cost optimization practices. Develops AI gateways with governance and security controls, internal developer platforms, CI/CD tooling, and automation to reduce toil. Partners across engineering, mentors SREs, influences technical direction, and leads complex infrastructure initiatives.
Top Skills:
AnthropicArgocdAtlantisAWSBedrockDatadogGithub ActionsGoKubernetesMcpPostgresPythonTerraformTypescript

Other
Lead the evolution of the Password Safe platform and infrastructure across cloud and on-premises environments. Design highly available systems, optimize platform services, standardize CI/CD and infrastructure-as-code practices, and establish GitOps workflows. Build observability, SLOs, chaos engineering, and disaster recovery capabilities. Serve as a technical leader by defining SRE strategy, mentoring engineers, conducting design and incident reviews, and influencing the engineering roadmap.
Top Skills:
AnsibleApi GatewaysAWSAzureC#Chaos EngineeringCi/CdDatadogDevsecopsDisaster RecoveryDockerGitopsGoGrafana CloudJavaKubernetesLinuxMicroservicesOpentelemetryOpentofuService MeshesTerraformWindows

Artificial Intelligence • Fintech • Software • Financial Services
Own and define Hanover Park’s infrastructure strategy as the company scales. Responsibilities include AWS, PostgreSQL, Supabase, Vercel, and Trigger.dev infrastructure; CI/CD; observability; security; backups; performance; incident response; SLOs and SLIs; and production reliability. The role also requires application coding, architecture decisions, automation, mentoring, and establishing platform engineering practices from the ground up.
Top Skills:
AlertingAWSCi/CdLoggingMonitoringObservabilityPostgresSecrets ManagementSlisSlosSoc 2SupabaseTerraformTracingTrigger.DevTypescriptVercel
Healthtech • Information Technology • Software • Telehealth
Designs and operates observability, automation, infrastructure as code, CI/CD, and reliability practices for distributed AWS systems. Partners with engineering teams to improve service visibility, scalability, performance, networking, deployment safety, incident response, and operational ownership. Participates in on-call rotations, leads incident response when needed, and drives blameless post-mortem remediation. Develops reusable platform standards for containers, service communication, secrets, routing, and production readiness.
Top Skills:
AWSCloudFormationDnsDockerGithub ActionsGitopsGoHttp/HttpsIngress ControllersJavaKubernetesLoad BalancersNtpOpentofuPythonReverse ProxiesRubyTcp/IpTerraformTlsWeb Application Firewalls

Agency • Information Technology
Site Reliability Engineer responsible for improving the reliability, resiliency, observability, and operational stability of large-scale application and platform environments. Duties include monitoring, alerting, incident response, troubleshooting, root-cause analysis, automation, performance and capacity analysis, operational readiness, and collaboration with application, infrastructure, and platform teams. The role requires strong production engineering experience, cloud platform knowledge, infrastructure-as-code familiarity, and secure operational practices.
Top Skills:
Api TestingDatadogGCPGitGrafanaInfrastructure As CodeJIRAUnit Testing

Cloud • Information Technology • Internet of Things • Professional Services • Software
Lead the architecture, operation, and reliability of Cisco ThousandEyes’ FedRAMP-compliant US GovCloud platform. Design resilient AWS services using infrastructure as code, maintain high availability and security for large-scale data streams, automate compliance controls and auditing, and collaborate with engineering and security teams on multi-region infrastructure, risk management, incident response, and technical strategy.
Top Skills:
AWSFedrampHipaaKubernetesPci-DssPythonSoc 2Terraform

28 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Build and operate security infrastructure protecting MongoDB Atlas across AWS, Azure, and GCP. Responsibilities include hardening Linux hosts and containers, implementing Kubernetes security controls, managing CSPM and workload identity platforms, deploying security controls through Terraform and other IaC tools, and creating monitoring and alerting systems. The role leads initiatives from threat modeling and architecture through implementation, rollout, and ongoing production reliability.
Top Skills:
AnsibleApparmorAWSAzureCC++CgroupsCiliumCloudFormationEbpfFalcoGatekeeperGoGoogle Cloud Platform (Gcp)KubernetesLinuxPythonRbacRustSeccompSelinuxTerraformTetragon

AdTech • Digital Media • Marketing Tech
Own the reliability, performance, and scalability of Vue 3 applications, headless WordPress platforms, and advertising technology infrastructure. Responsibilities include managing Cloudflare CDN and Workers, GCP services, Terraform, CI/CD pipelines, Prebid.js monetization, OpenTelemetry monitoring, Core Web Vitals, and incident post-mortems. The role also leads engineering initiatives and supports performance-focused team practices.
Top Skills:
Cloud RunCloudflare CdnCloudflare WafCloudflare WorkersComposition ApiGithub ActionsGitlab CiGkeGoogle Ad ManagerGoogle Cloud PlatformGraphQLLinuxOpentelemetryPrebid.JsTerraformViteVue 3WordpressWp Rest Api

Big Data • Cloud • Hardware • Software • App development
Designs, builds, and operates observability and SRE systems that improve IT service visibility, reliability, performance, and resilience. Responsibilities include metrics collection, monitoring, alerting, APM, RUM, synthetic transactions, SLOs, incident response, capacity planning, infrastructure automation, self-healing systems, and production readiness reviews. The role also applies AI-enabled operations, supports on-call rotations, reduces operational toil, and partners with development teams on architecture and chaos testing.
Top Skills:
AgileAiopsAnsibleApmAWSAzureBigpandaChaos EngineeringCi/CdDistributed TracingDockerElkGCPGitGitGoGrafanaInfrastructure As CodeKubernetesLinuxMachine LearningOpentelemetryPodmanPrometheusPythonRumSplunkSynthetic Transaction MonitoringTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free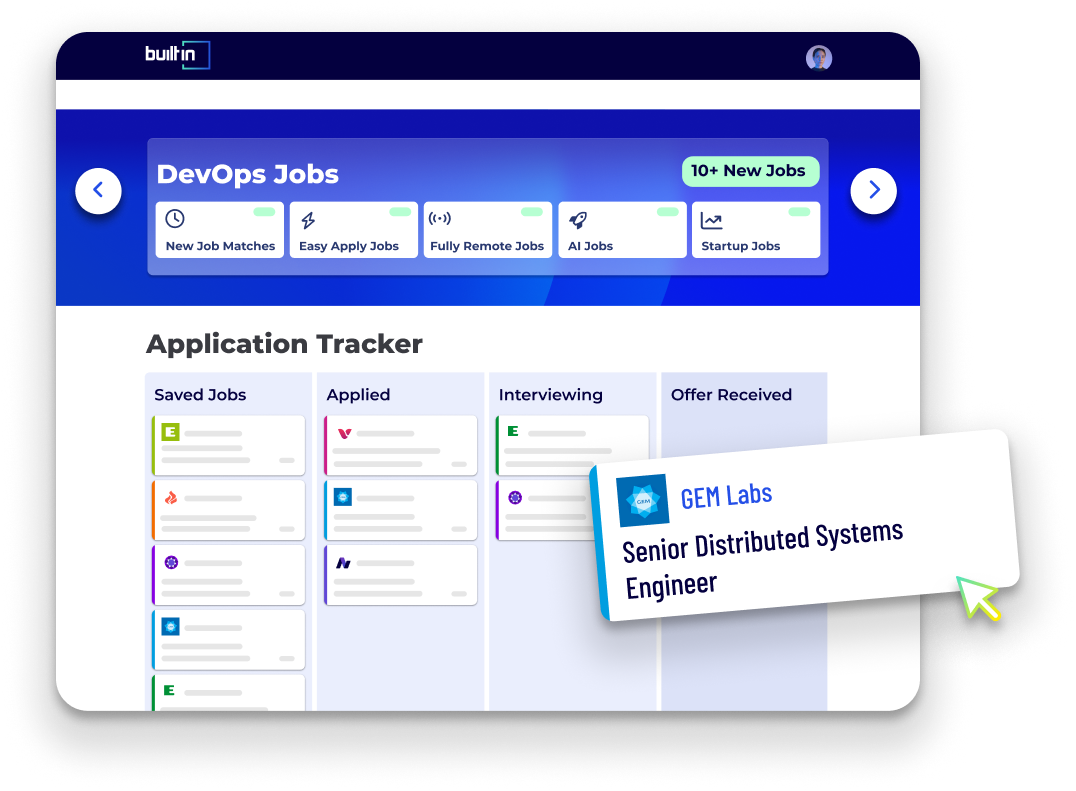

Greentech • Energy
Own end-to-end SRE projects and hybrid infrastructure across AWS, Azure, and on-premises environments. Lead architecture, Terraform-based infrastructure, CI/CD, observability, FinOps, database reliability, security, incident response, automation, and documentation. Serve as a technical anchor through design reviews, complex debugging, mentorship, and platform strategy while participating in on-call and post-incident improvements.
Top Skills:
AWSAzureCi/CdKubernetesMssqlMySQLOn-Premises InfrastructurePostgresSnowflakeTerraformVault
Artificial Intelligence • Cloud • Information Technology • Consulting
Internship SRE role responsible for availability, performance, and scalability of an e-commerce supply-chain platform. Tasks include SLO/SLA definition, observability (Prometheus/Grafana/Loki/Tempo/OpenTelemetry), incident response, capacity planning, disaster recovery for PostgreSQL, infrastructure-as-code (Terraform), CI/CD automation, and operational reliability for AI agent services. Mentored by Head of Technology/CTO with potential conversion to full-time based on performance.
Top Skills:
BashCi/CdDockerGrafanaLangchainLlmLokiMakefileNestjsOpentelemetryOracle CloudPgbackrestPostgresql 15PrometheusPythonRedisTempoTerraformTraefik

Robotics
Own and scale cloud infrastructure supporting machine learning and robotics teams. Design reliable distributed systems, build observability across monitoring, logging, and tracing, implement infrastructure as code, improve security and incident response, and optimize performance and cloud costs across AWS, GCP, and Azure.
Top Skills:
AWSAzureDatadogGCPKubernetesPrometheusSplunkTerraform
Fintech • Financial Services
Develops automation and internal tools with Python and Java, integrates workflows with ServiceNow, supports CI/CD pipelines and deployments, and automates infrastructure operations. The role also handles capacity monitoring, cloud and container technologies, Infrastructure as Code, observability, troubleshooting, and reliability improvements while collaborating with SRE, application, infrastructure, and platform teams.
Top Skills:
Ci/CdCloud TechnologiesDevOpsDockerInfrastructure As CodeJavaKubernetesLinuxMonitoring And Observability ToolsPythonRest ApisServicenowUnix

Fintech • Payments
Lead the vision, strategy, and organizational growth of Payments SRE across reliability, observability, automation, incident management, performance, capacity planning, and disaster recovery. Manage SRE leaders and engineers supporting high-availability, low-latency payment systems. Partner with executives and engineering and product teams, drive compliance and operational excellence, mentor leaders, build reliability frameworks, and advance AI-enabled operations.
Top Skills:
Ai/MlCloud-Native ArchitectureDistributed SystemsDistributed TracingDockerElk StackGrafanaKubernetesMySQLNetworkingNoSQLPci-DssPostgresService MeshesSplunkStorage Architectures

Cloud • Information Technology
Lead the Site Reliability Engineering organization, managing and developing technical teams while driving reliability, scalability, observability, automation, and operational excellence. Responsibilities include infrastructure automation, vulnerability management, incident response, SLA and SLO analysis, monitoring improvements, post-incident reviews, ITIL processes, vendor coordination, and cross-functional reliability initiatives for large-scale production storage systems.
Top Skills:
AWSGoogle Cloud PlatformGrafanaIpvsItilLinuxAzureOpensearchPrometheusVictoriametrics

Reposted 27 Days AgoSaved
Fintech • Financial Services
Leads the global Site Reliability Engineering function for an event-driven platform. Responsibilities include building and managing the SRE team, setting reliability strategy, guiding architecture and code reviews, improving AWS infrastructure, Kafka and PostgreSQL resilience, strengthening CI/CD and release engineering, establishing SLOs and observability, reducing operational toil, coordinating incident response, and enabling responsible AI adoption.
Top Skills:
APIsAWSCi/CdDistributed TracingDockerEcsEksGitIamInfrastructure As CodeJavaKafkaKafka ConnectKubernetesLambdaOpentelemetryPostgresSpring BootSQLTerraform

Aerospace • Information Technology • Security • Cybersecurity • Defense
Designs and develops Python-based reliability tools and cloud solutions on AWS using Terraform. Builds automation, observability, CI/CD pipelines, and testing frameworks; defines SRE standards, SLIs, SLOs, and error budgets; participates in incident response, on-call support, root-cause analysis, and postmortems. Collaborates across Agile teams to improve platform reliability, reduce toil, optimize cloud costs, and advance cloud-native engineering practices.
Top Skills:
Amazon Ec2Amazon EventbridgeAmazon S3Amazon VpcAWSAws CanaryAws CloudformationAws CloudwatchAws IamAws LambdaAws Step FunctionsCi/CdGoGrafanaInfrastructure As CodePythonTerraform

Fintech • Information Technology • Insurance • Financial Services • Big Data Analytics
Leads architecture, modernization, optimization, and reliability initiatives for mainframe CICS, MQ, and z/OS Connect environments. Provides technical direction across development and operations teams, establishes governance and change processes, tunes performance using telemetry, resolves incidents, and develops modernization roadmaps. Collaborates with stakeholders and enterprise architects to deliver secure, scalable, high-availability solutions while evaluating automation, cloud integration, and AI technologies.
Top Skills:
AnsibleCicsCobolDevOpsIbm MqIbm Z/OsOpenshiftPythonRed Hat Ansible Automation PlatformZ/Os ConnectZlinux
Reposted One Month AgoSaved
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Leads teams designing and deploying AI-driven enterprise and cloud security solutions. Responsibilities include developing machine learning systems, integrating data infrastructure and pipelines, performing advanced modeling and analysis, and building AI applications with Python, Java, and C++. The role involves client engagement, strategic problem-solving, stakeholder validation, coaching, process innovation, and operational excellence while addressing complex cybersecurity and privacy challenges.
Top Skills:
Ai SystemsAWSC++Cloud SecurityData EngineeringData PipelinesDatabricksGCPJavaMachine LearningAzurePythonScikit-LearnSnowflakeTensorFlow

Artificial Intelligence • Big Data • Cloud • Information Technology
Own end-to-end client support, troubleshoot production issues, monitor cloud environments, respond to incidents, automate operational tasks, and lead postmortems. Develop and execute manual and automated QA tests, maintain regression suites, integrate testing into CI/CD, and validate AI-powered features. Build documentation, collaborate with engineering and product teams, and improve reliability for regulated-industry clients.
Top Skills:
Ai/LlmAWSAzureAzure MonitorBashCi/CdCloudwatchKubernetesPlaywrightPowershellPythonSQLTerraform

Healthtech • Software
Staff Site Reliability Engineer responsible for setting infrastructure direction and owning availability, stability, scalability, observability, disaster recovery, and cloud costs for a SaaS platform. The role involves multi-cloud architecture, managed Kubernetes, infrastructure automation, GitOps delivery, incident response, business continuity, technical evaluations, platform migrations, and mentoring engineers. This is a fully remote U.S.-based position with an on-call rotation.
Top Skills:
Cloud ComputingGitopsInfrastructure As CodeKubernetesObservabilityScripting

Healthtech
Lead the evolution of Azure infrastructure toward Kubernetes-based, microservices-oriented systems. Design reliable and scalable cloud infrastructure, observability, networking, CI/CD pipelines, and Infrastructure-as-Code. Drive incident response, cost optimization, capacity planning, performance improvements, and automation while partnering with engineering and data teams. Document best practices, mentor colleagues, and support platform strategy in a healthcare environment with PHI, access control, and audit requirements.
Top Skills:
.NetAWSAzureAzure Entra IdBashC#DatadogGCPGithub ActionsGitlab Ci/CdGrafanaHelmKubernetesPrometheusPythonTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top NYC Companies Hiring Senior Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs in NYC
.NET Developer Jobs in NYC
Android Developer Jobs in NYC
C# Jobs in NYC
C++ Jobs in NYC
DevOps Jobs in NYC
Engineering Manager Jobs in NYC
Front End Developer Jobs in NYC
Golang Jobs in NYC
Hardware Engineer Jobs in NYC
iOS Developer Jobs in NYC
Java Developer Jobs in NYC
Javascript Jobs in NYC
Linux Jobs in NYC
Perl Jobs in NYC
PHP Developer Jobs in NYC
Python Jobs in NYC
QA Jobs in NYC
Ruby Jobs in NYC
Sales Engineer Jobs in NYC
Salesforce Developer Jobs in NYC
Scala Jobs in NYC
Artificial Intelligence Jobs in NYC
Artificial Intelligence Engineer Jobs in NYC
AWS Engineer Jobs in NYC
Backend Engineer Jobs in NYC
DevOps Engineer Jobs in NYC
Director of Engineering Jobs in NYC
Engineering Jobs in NYC
Full Stack Engineer Jobs in NYC
Infrastructure Engineer Jobs in NYC
Lead Software Engineer Jobs in NYC
Network Engineer Jobs in NYC
Platform Engineer Jobs in NYC
Principal Architect Jobs in NYC
Principal Engineer Jobs in NYC
Principal Software Engineer Jobs in NYC
Quality Assurance Automation Engineer Jobs in NYC
Reliability Engineer Jobs in NYC
Senior Backend Engineer Jobs in NYC
Senior Cloud Engineer Jobs in NYC
Senior Full-Stack Engineer Jobs in NYC
Senior Platform Engineer Jobs in NYC
Senior Python Engineer Jobs in NYC
Senior Site Reliability Engineer Jobs in NYC
Solutions Architect Jobs in NYC
Solutions Engineer Jobs in NYC
Staff Engineer Jobs in NYC
Staff Software Engineer Jobs in NYC
Systems Engineer Jobs in NYC
Vice President of Engineering Jobs in NYC
All Filters
Total selected ()
No Results
No Results
